


Image: @OpenAIDevs (X) (video still)
Summary
- OpenAI launched Ultrafast for GPT-6.1 Sol on October 8, running up to 8x faster than Sol Standard and rolling out across the API, Codex and ChatGPT Work.
- API pricing is $12 per million input tokens and $60 per million output tokens, six times the standard rate, and in Codex and ChatGPT Work it is limited to Pro 500 and some Enterprise and Edu plans.
- Sol Ultrafast's per-minute token limit reaches 40 million at the Grow tier, eight times Astra Ultrafast, and it supports both US and EU data residency.
OpenAI launched Ultrafast for GPT-6.1 Sol on October 8 (local time). OpenAI's developer account said on its official X account that day that Ultrafast is rolling out across the API, Codex and ChatGPT Work and runs up to 8x faster than Sol in standard mode. API pricing is $12 per million input tokens and $60 per million output tokens. The speed tier OpenAI first attached to its top model, GPT-6 Astra, at DevDay on September 29 has moved one step down the lineup nine days later.
METAL reported that OpenAI launched the Ultrafast speed tier at DevDay, when the company said Ultrafast for GPT-6.1 Sol would follow soon. GPT-6.1 Sol, released the same day, is pitched as delivering performance close to Astra at a lower price. METAL also covered the GPT-6.1 Sol release. With this launch, OpenAI's Ultrafast lineup now spans two models, Astra and Sol.
In the launch post, OpenAI's developer account wrote that Ultrafast delivers "near-Astra intelligence at up to 8x faster speeds than Sol Standard" so "you can build as fast as the ideas come." In a follow-up pricing post, it said Ultrafast was built for "work where speed and intelligence make a difference." The company's examples were debugging an outage, agents navigating apps and live experiences where every second counts.
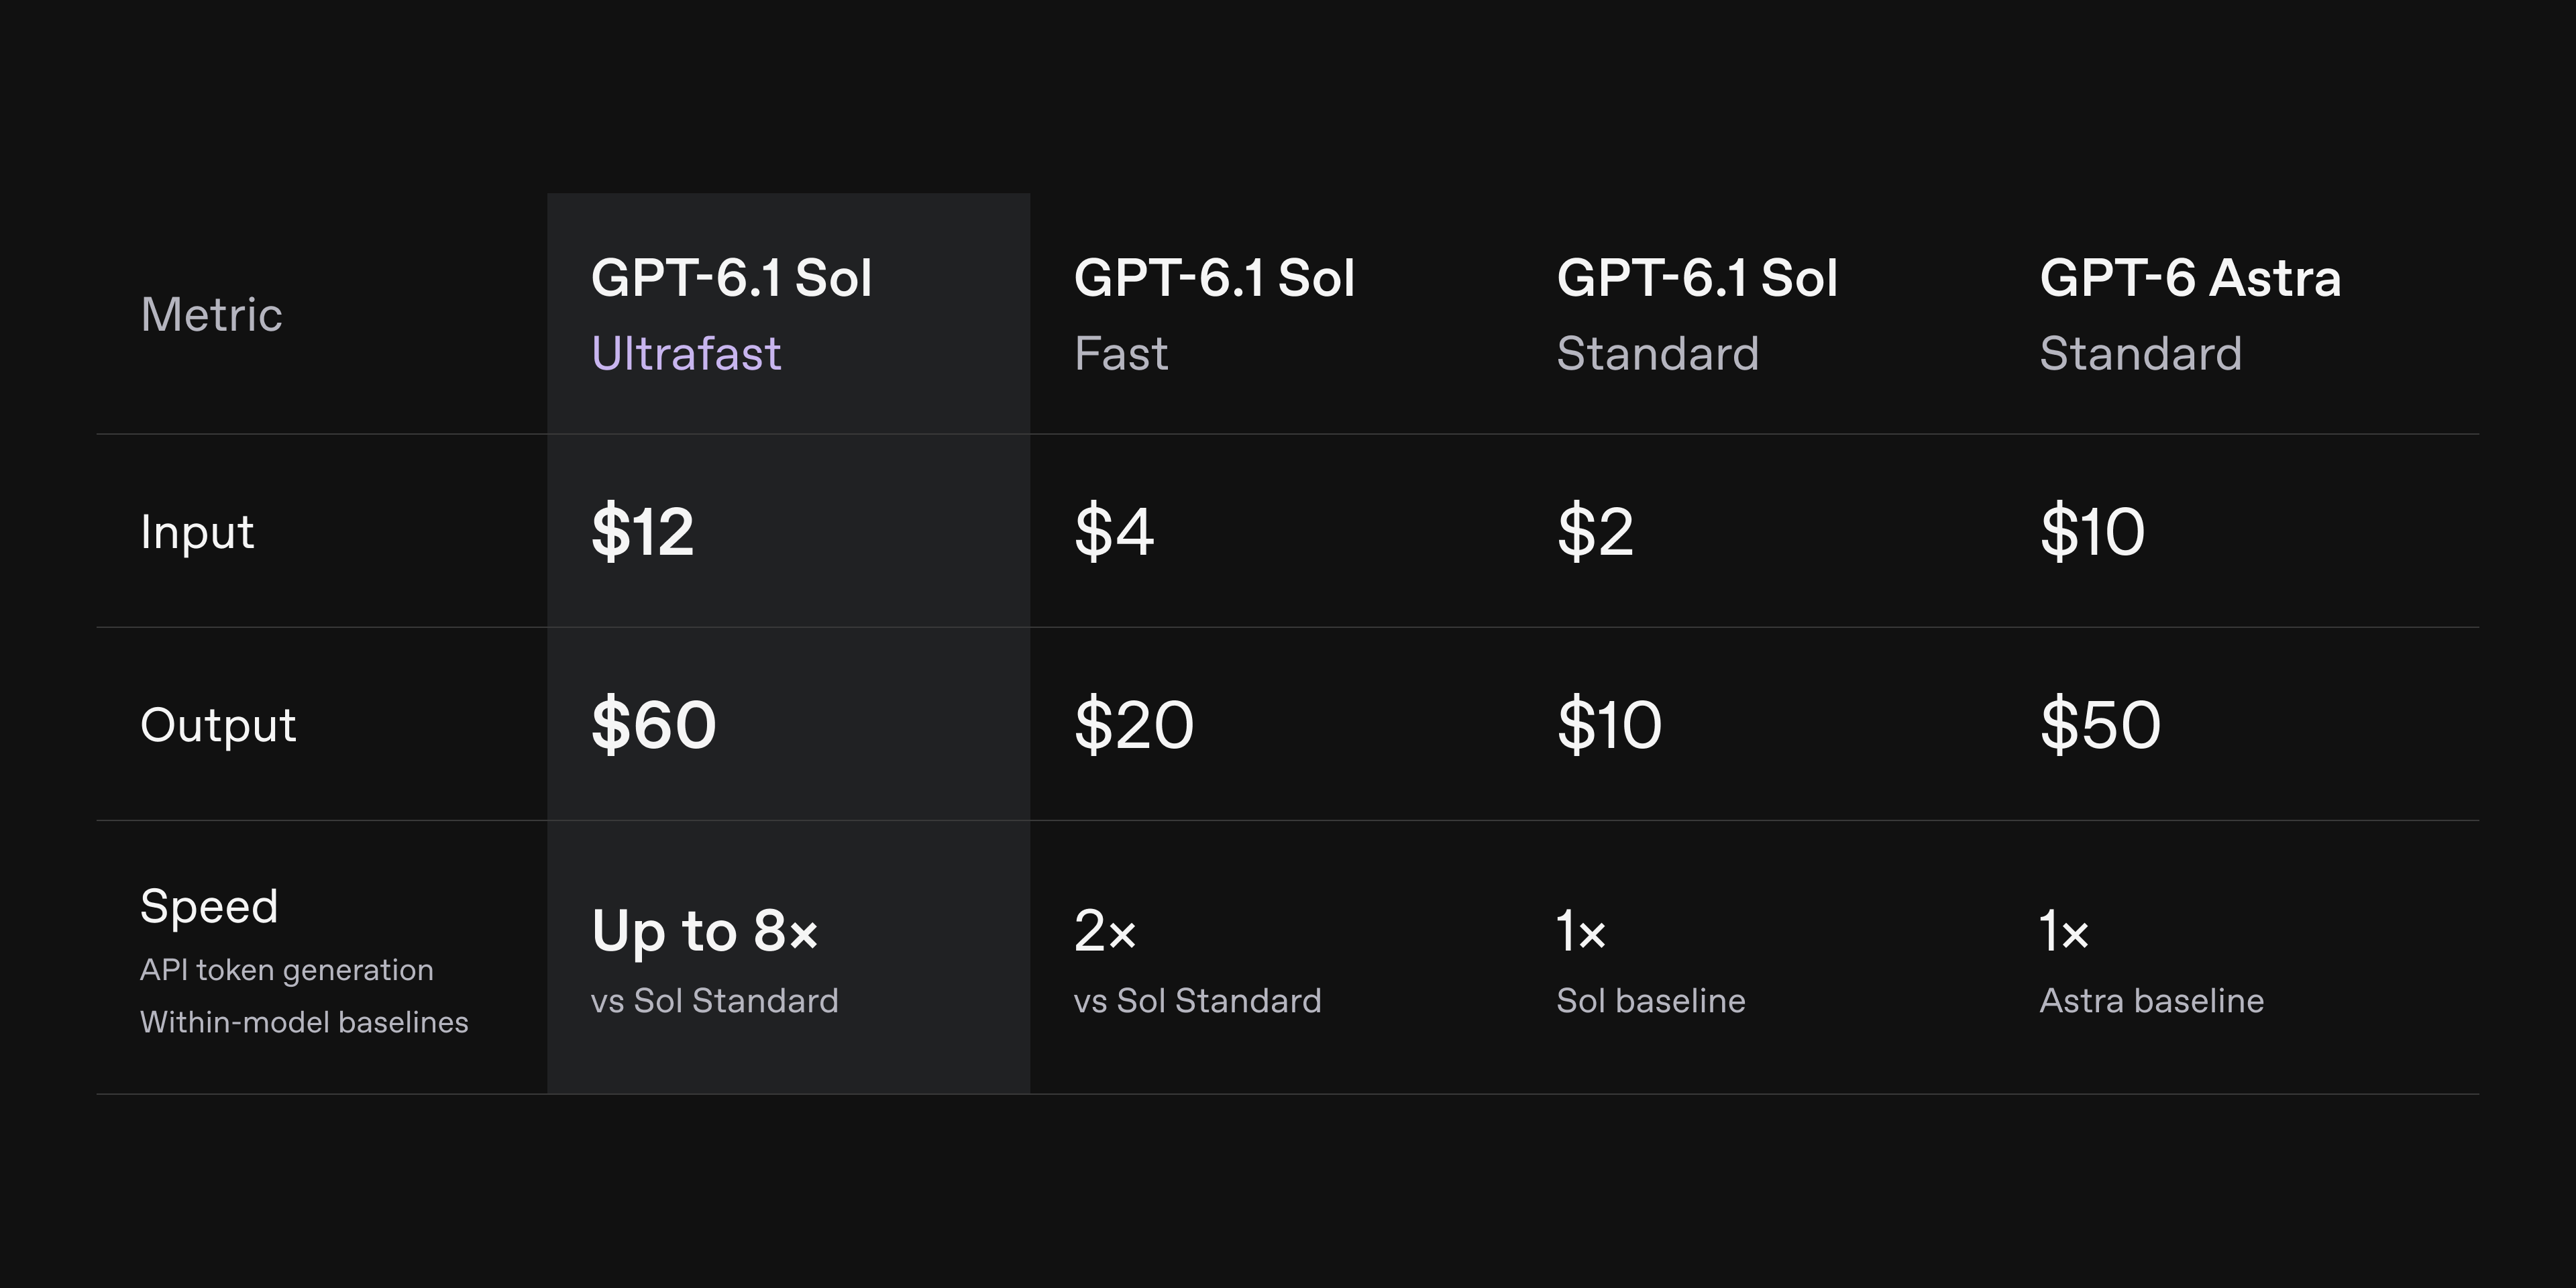
The price rises with the speed. According to an OpenAI pricing chart reviewed by METAL, GPT-6.1 Sol's standard API price is $2 per million input tokens and $10 per million output tokens, and the 2x-faster Fast mode costs $4 and $20. Ultrafast, at up to 8x the speed, costs exactly six times standard. The same chart lists GPT-6 Astra's standard price at $10 for input and $50 for output, so Sol Ultrafast is 1.2 times as expensive as Astra Standard. Running the smaller model fast costs slightly more than running the smarter flagship at standard speed. According to reports, cached input costs $0.60 per million tokens and cache writes $15, prompts longer than 272,000 input tokens carry different rates, and choosing regional processing adds 10%.
OpenAI's API guide, reviewed by METAL, describes Ultrafast as the fastest service tier in the API and says to use it "when speed justifies the higher cost." It is broadly available for GPT-6 Astra and GPT-6.1 Sol, with preview access for GPT-5.6 Sol. Developers set the model to gpt-6.1-sol and the service_tier value to ultrafast. Ultrafast for Astra and Sol is open to all API users and has rate limits separate from Standard and Fast modes.
Sol gets far more headroom. According to the guide, GPT-6.1 Sol Ultrafast's default limits are 1 million tokens per minute at the Build tier, 4 million at Launch and 40 million at Grow. At the same tiers, Astra Ultrafast is capped at 500,000, 1 million and 5 million, so the gap widens from 2x to 4x to 8x as tiers rise. Data handling also differs: Sol Ultrafast supports US and EU data residency as well as global processing, while Astra Ultrafast supports only US residency and global processing.
OpenAI strongly recommended that agents making frequent tool calls use WebSockets to keep a persistent connection, because opening a new connection for each request lets network latency eat into the speed gain. The guide includes sample code that chains multiple turns over one WebSocket connection by passing the previous response's ID.
The bar is higher in Codex and ChatGPT Work. According to reports, Sol Ultrafast in those two products is available only on the Pro 500 plan, eligible usage-based Enterprise plans and credit-based Edu plans, and Enterprise administrators must enable it themselves. Pro 500 launched alongside Astra Ultrafast at DevDay on September 29 and is the only route to Ultrafast for individual users in those products.
The 14-second launch video reviewed by METAL has no sound. On a black screen, an English sentence introducing GPT-6.1 Sol in standard mode types out letter by letter over nearly two seconds and then fades. The same sentence ending in Ultrafast mode then appears all at once in under half a second. The video closes with a line inviting viewers to try it in Codex, ChatGPT Work and the API today. Within two hours of posting, the launch post with the video had drawn 320,000 views and more than 2,800 likes.
From an engineer's point of view, the key to this launch is less the speed than the limits and data location. Astra Ultrafast's low limits at the upper tiers and lack of EU data residency were obstacles to large-scale operation. With up to 8x more headroom and EU residency, Sol Ultrafast is configured to carry real production traffic. The remaining calculation is identifying which calls have latency that shapes the user experience enough to justify a sixfold price.
Sources
- OpenAI Developers (X) — Ultrafast is rolling out today for GPT-6.1 Sol in the API, Codex, and ChatGPT Work. →
- OpenAI Developers (X) — API pricing for GPT-6.1 Sol in Ultrafast mode →
- OpenAI — Ultrafast mode | OpenAI API →
- RuntimeWire — OpenAI adds GPT-6.1 Sol Ultrafast at six times standard API prices →
- TokenPost — OpenAI Rolls Out GPT-6.1 Sol Ultrafast Mode at Up to 8x Speed →
Comments