


Summary
- Ai2 releases preview of TutorMoments, an AI tutor evaluation framework built from real tutoring sessions
- LLMs showed a default tendency to over-help, and even when scoring criteria were spelled out in the prompt, they still fell short of the varied strategies human tutors use
- Dataset, code, and model replays are all open, though the current preview is limited to early-stage US K-12 math
The core dilemma AI tutors must solve
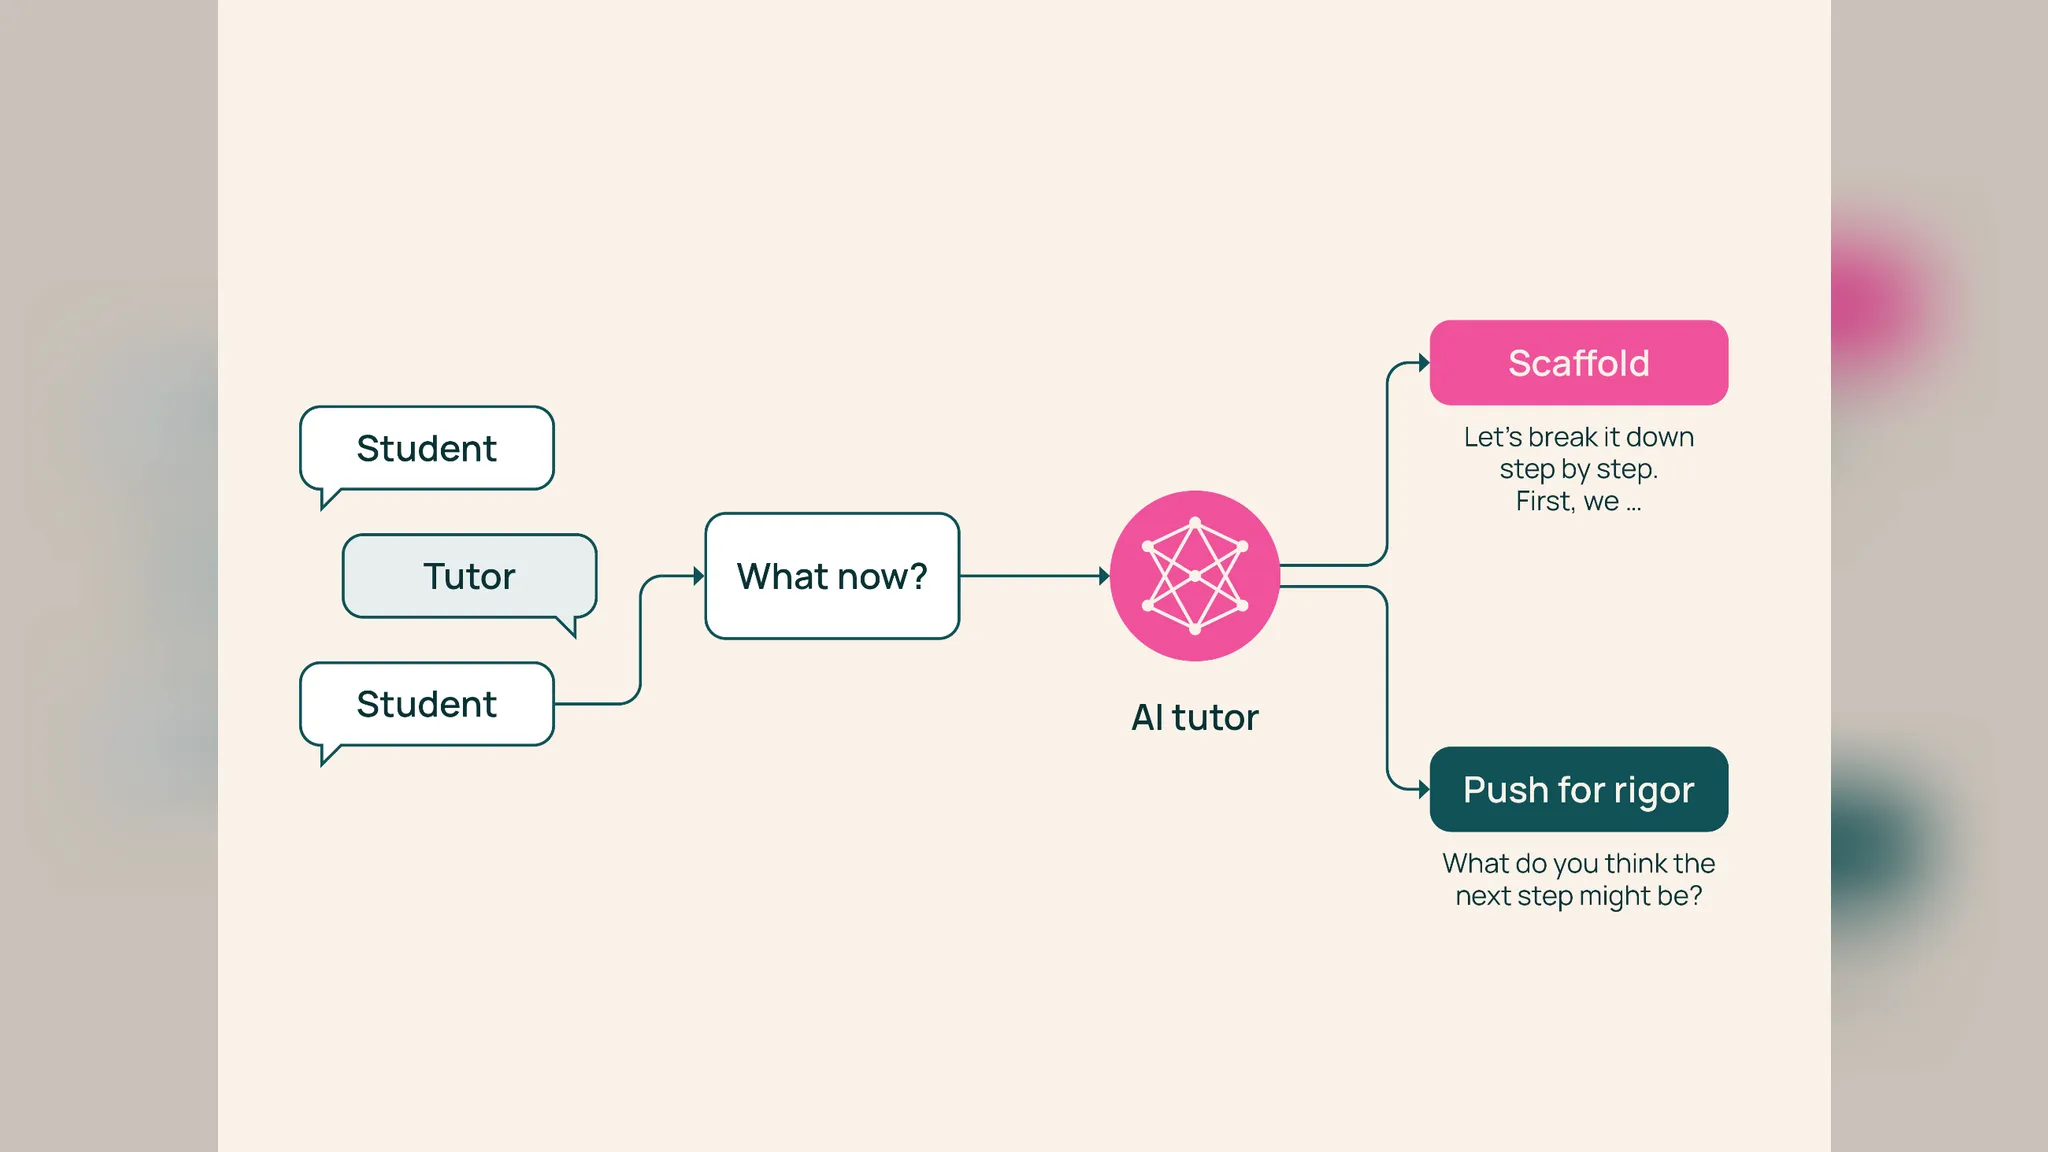
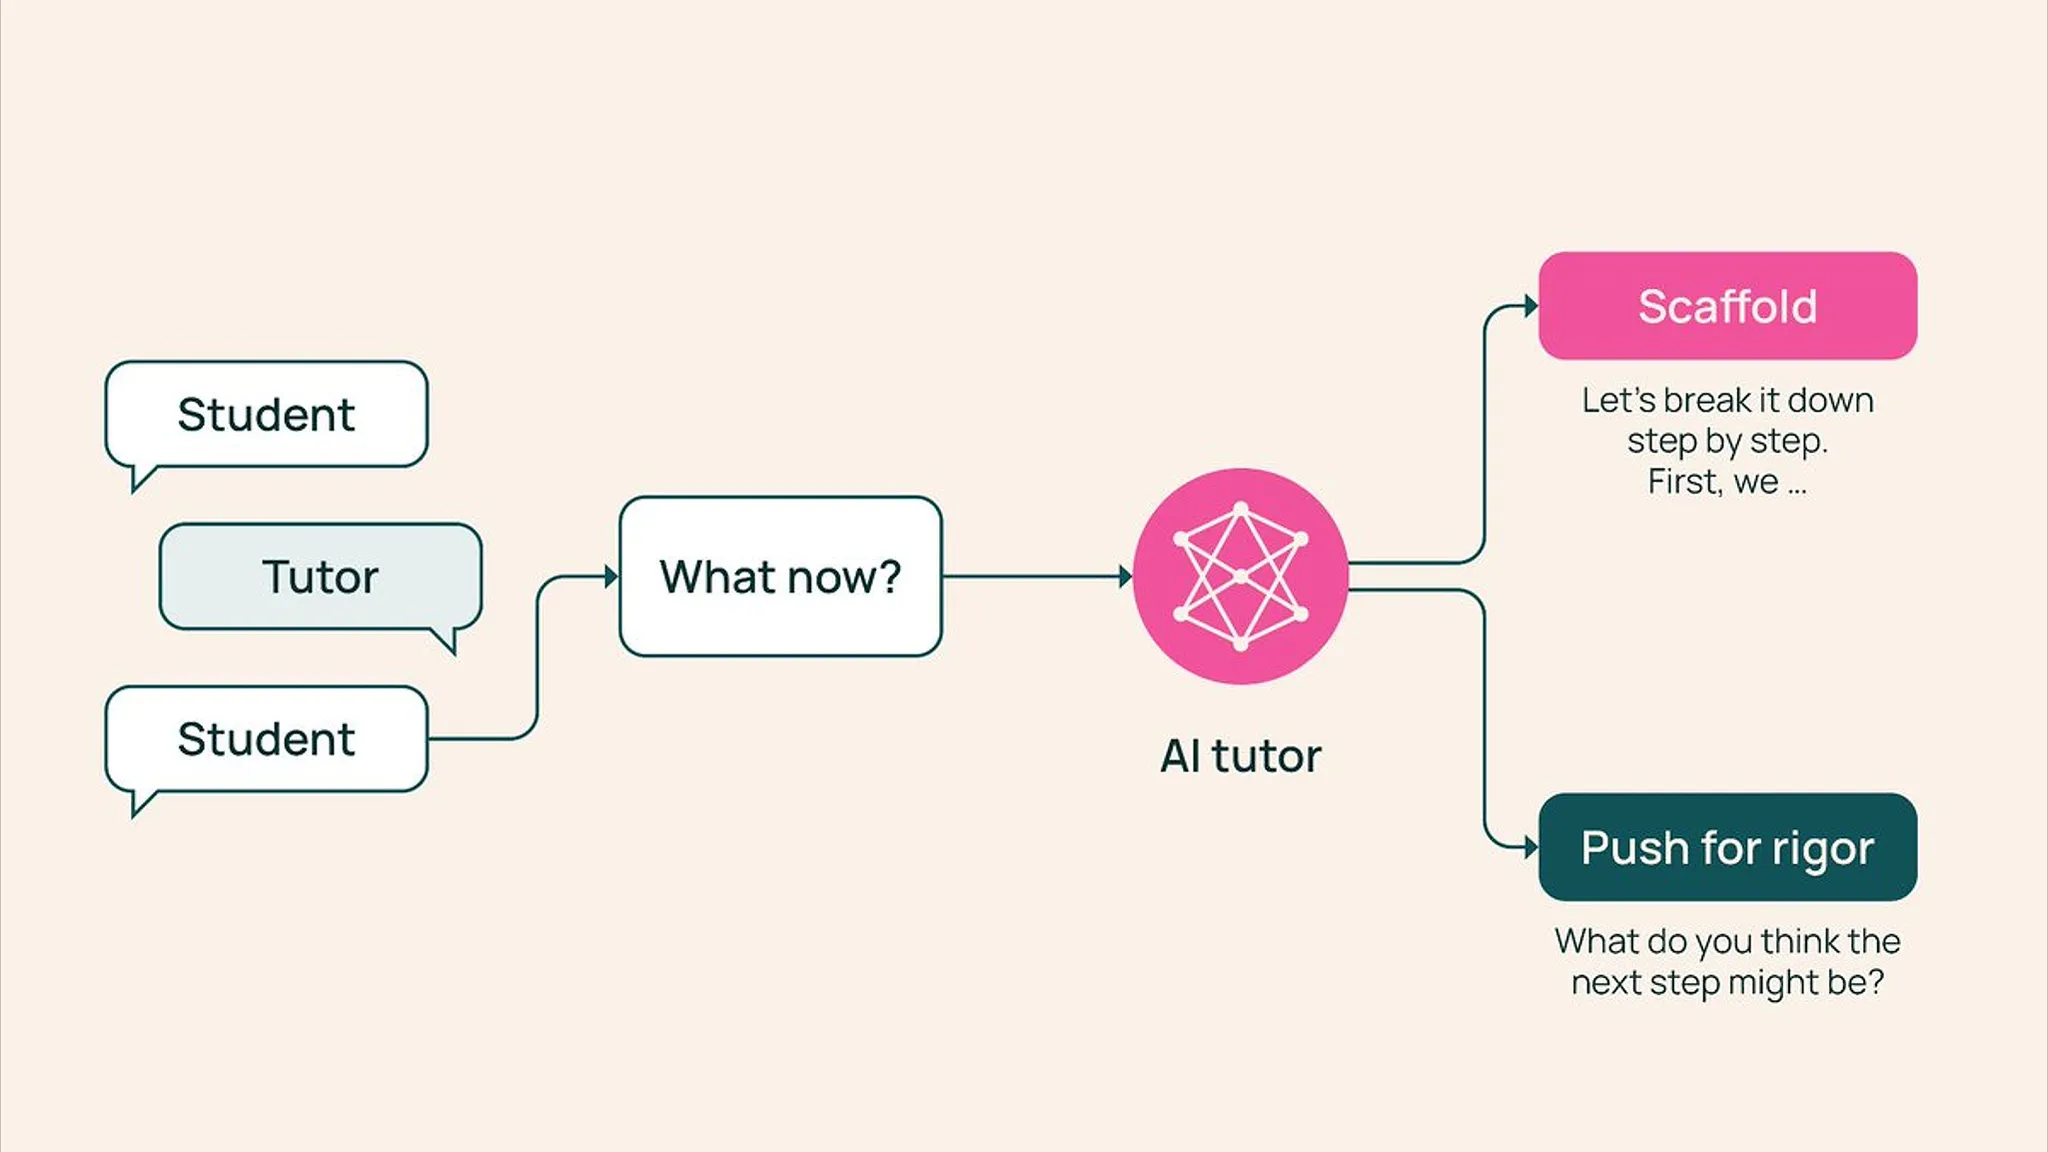
A good math teacher doesn't hand over the answer the moment a student gets stuck. Instead, they turn the question back — "What do you already know about this problem?" — prompting the student to think it through themselves. But if the student already understands the material well, pushing them toward harder reasoning is more effective. Striking this balance between "scaffolding" and "rigor" is central to good tutoring, yet it's a balance language models are structurally ill-equipped to strike.
LLMs are trained to be "helpful" assistants. Explaining concepts, listing steps, and guiding toward an answer is their default behavior. But in a tutoring context, this behavior can short-circuit the "productive struggle" a student needs to work through on their own — a process that learning research has long identified as key to deepening understanding.
How TutorMoments is structured
TutorMoments is built from real one-on-one math tutoring sessions collected through a US tutoring program. The released preview dataset, TutorMoments-Preview, contains 462 one-on-one math tutoring sessions with students in US grades 2 through 7, more than 1,500 key decision points flagged by 27 practicing US teacher-annotators, and thousands of free-text annotations. Most transcripts come from a high-intensity tutoring program serving students at Title I schools (schools serving low-income student populations), and were provided with parent/guardian consent. Personally identifiable information was first removed by the providing organization, then scrubbed again by Ai2 using a math-specific pipeline.
The evaluation method is a "replay" approach. Transcripts are paused at key decision points, and a language model takes over the tutor role, continuing a five-turn conversation with a simulated student played by another language model. An LLM-based grading pipeline then scores each replay against three criteria: first, whether support was provided when the student needed it (appropriate scaffolding); second, whether more challenge was introduced when the student was ready for it (appropriate rigor); and third, whether the problem was made easier than the situation called for (avoiding over-scaffolding). The ground-truth labels used for grading come from multiple teachers annotating each decision point, with disagreements resolved by majority vote.
Preliminary results across seven models
Ai2 evaluated seven LLMs on TutorMoments under two prompting conditions. One was a baseline prompt with no specific guidance — simply instructing the model to "tutor well." The other was an evaluation-aware prompt that explicitly explained the tradeoffs among scaffolding, over-scaffolding, and rigor. All scores range from 0 to 1, representing the proportion of decision points of a given type where the model behaved appropriately.
Human tutors were included not as an ideal benchmark but as a naturalistic reference point. Evaluated on the same decision points using the same scoring method, human tutors scored 0.458 on appropriate scaffolding, 0.182 on appropriate rigor, and 0.496 on avoiding over-scaffolding. These numbers are low in part because the dataset was deliberately built to capture moments where tutoring could have gone better — meaning it collects missed opportunities rather than exemplary practice.
The clearest pattern in the results is the effect of prompting. Under the evaluation-aware prompt, every model's scores improved over the baseline prompt, indicating that a model's default "helpful assistant" behavior alone is not sufficient for good tutoring. But making the tradeoffs explicit didn't fully close the gap with human performance. While models used rigor-demanding strategies more often under the evaluation-aware prompt, they drew on a much narrower range of strategies than human tutors, and rarely stepped back to let students work through problems on their own — something human tutors did far more often.
Scope of release and current limitations
Alongside this preview, Ai2 has released an anonymized tutoring-transcript dataset, the replay pipeline code, and the model tutor replay results at the evaluated decision points. The technical report is available at tutormoments.allen.ai, the dataset on Hugging Face, and the code on GitHub.
That said, there are several limitations at this stage. Automated evaluation can offer signal about how a model behaves at a given decision point, but it cannot substitute for research on actual learning outcomes with real students. The dataset is limited to the US, mostly K-12 math, and a single pool of annotators — making it hard to generalize results to other subjects, grade levels, or settings. Rigor scoring is less reliable than scaffolding scoring, and in the underlying annotations, rigor decision points (260) are fewer in number than scaffolding decision points (738).
Ai2 says it will use feedback from this preview to guide further development, aiming for a larger multimodal dataset, a stronger grading pipeline, and deeper analysis. The project was supported by the Gates Foundation and the Learning Commons.


Comments